
MiniMax H3 Image
提供:MiniMax
Sixteen reference images keep one face across every frame.
Native 4K, drawn in about twenty seconds.
主な特徴
One face, many frames
Give it up to sixteen reference images, such as a character sheet, a location and the previous frame, and it keeps the person, the costume and the room consistent from shot to shot.
Native 1K, 2K and 4K
Every size is generated at full resolution rather than upscaled. 4K is about sixteen megapixels, enough to crop a close-up out of a wide frame.
Fast
A 2K frame with two reference images came back in about twenty-three seconds in our test, two to three times faster than the GPT Image tier Dimly uses by default.
Range of looks
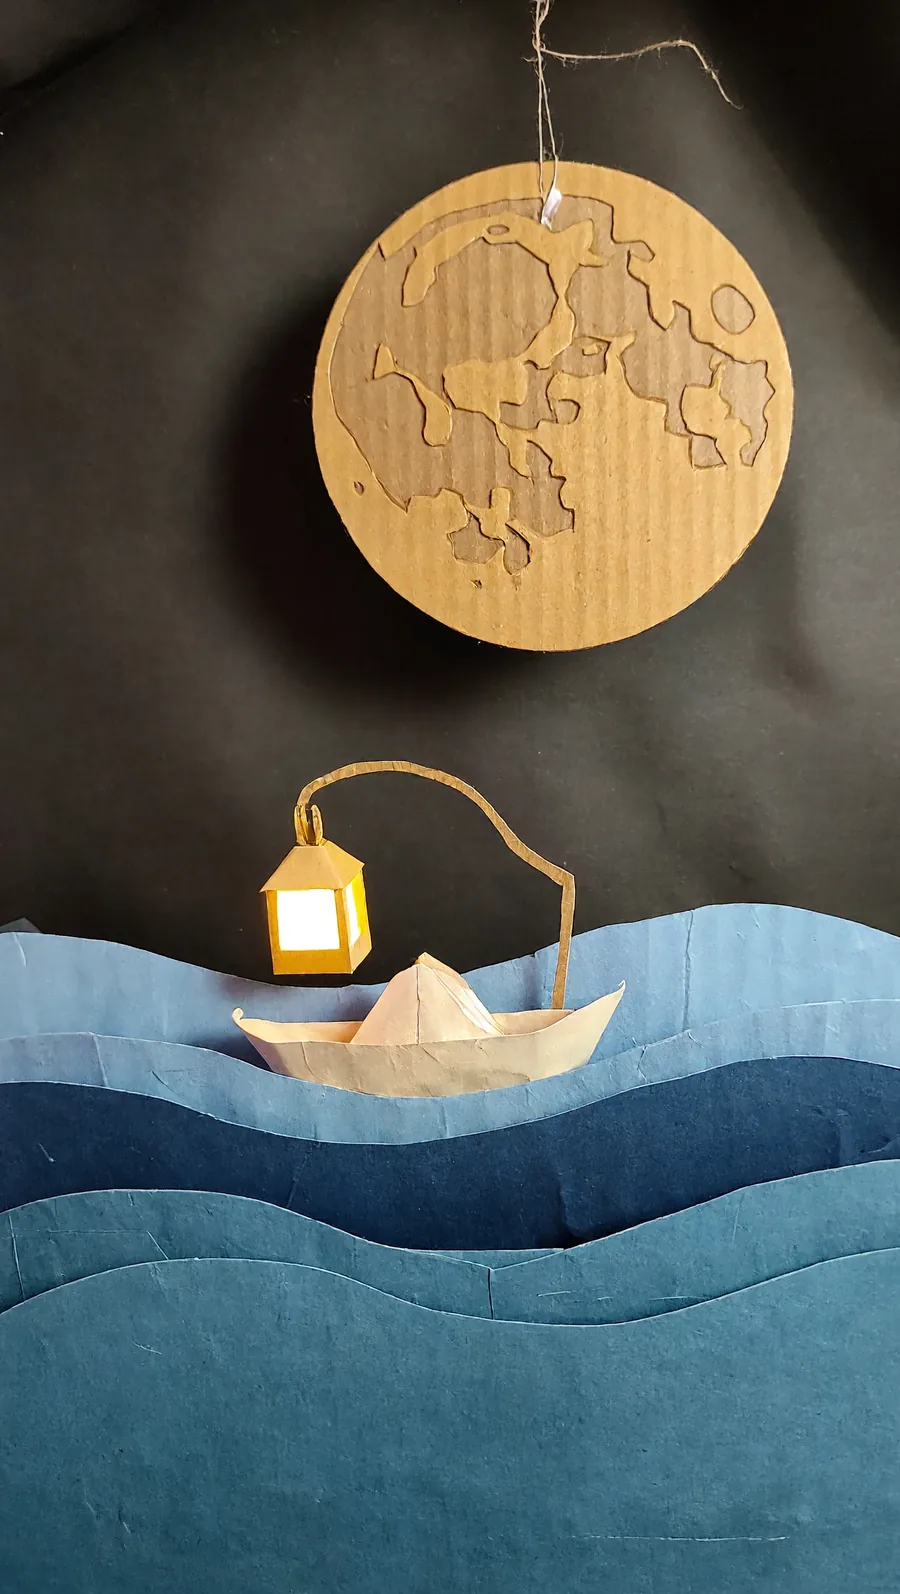
Film photography, painterly light, paper-cutout sets and neon nights from plain-language prompts, so a whole video can hold one visual language.
Chinese and English text
MiniMax pitches it on reasoned text rendering for signs and posters in both languages. Short words came out right in our tests, though it sometimes adds small made-up text around them.
Open weights
MiniMax publishes the weights: a 33-billion-parameter diffusion transformer that draws in six steps, from the same family as the H3 video model.
技術仕様
H3 Image
MiniMax's open-weights text-to-image and edit model
16 references
Public image URLs, up to 20 MB each
1K / 2K / 4K
About 1, 4 and 16 megapixels, all native
21:9 to 9:16
Eleven aspect ratios, or a custom size
~23 s
A 2K frame with two references, measured
PNG or JPEG
One image per request
5,000 characters
Prompt length, Chinese or English
6 steps
No negative prompt; describe what you want in the frame
プロンプト例
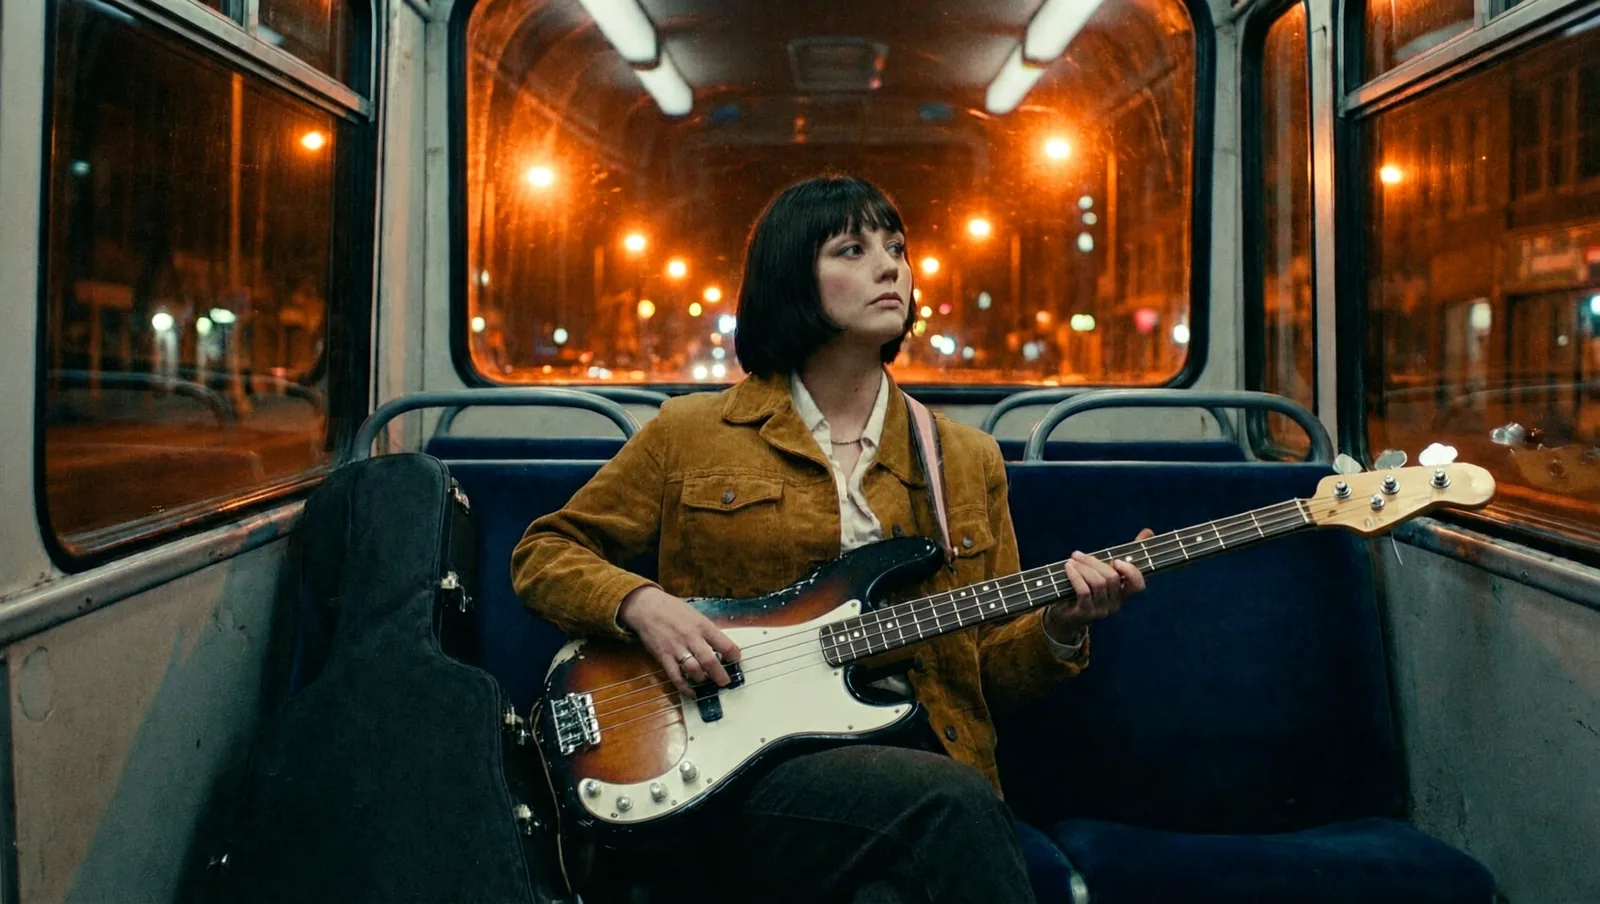
Night bus
She sits alone at the back of an empty night bus, bass case on the seat beside her, orange sodium streetlights streaking across the windows, looking out at the city
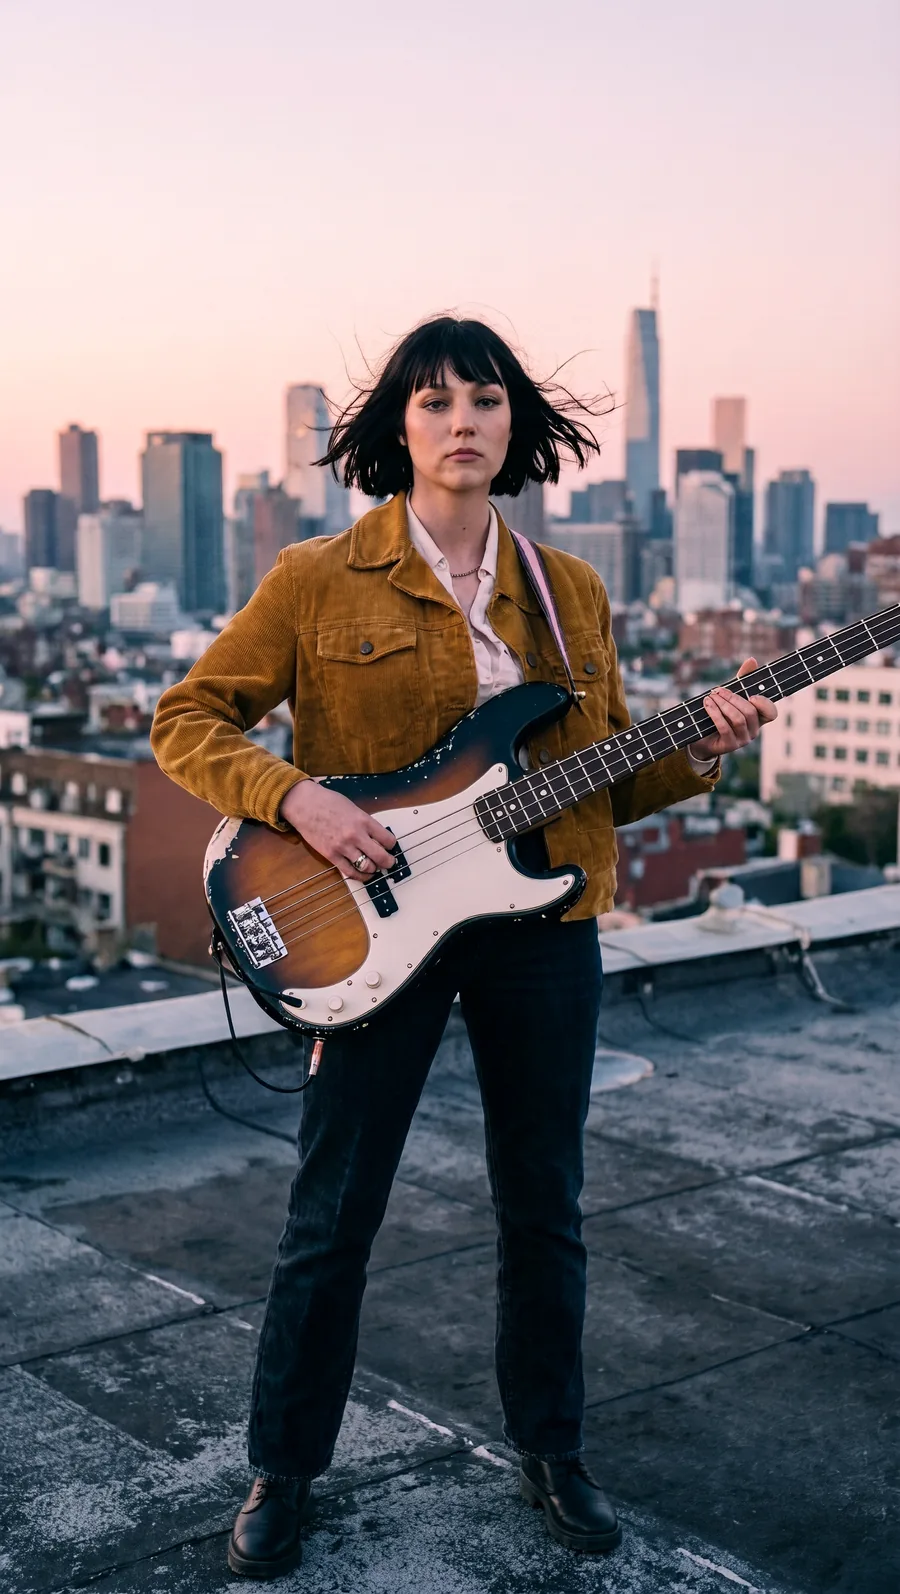
プロンプトを編集Rooftop at dawn
She stands on a tar rooftop at dawn playing the bass, the city skyline soft and pink behind her, wind in her hair. Vertical frame, full figure, natural light
プロンプトを編集Desert blue hour
A lone white tour van parked on an empty desert highway at blue hour, headlights on, a single figure sitting on the roof looking at the first stars
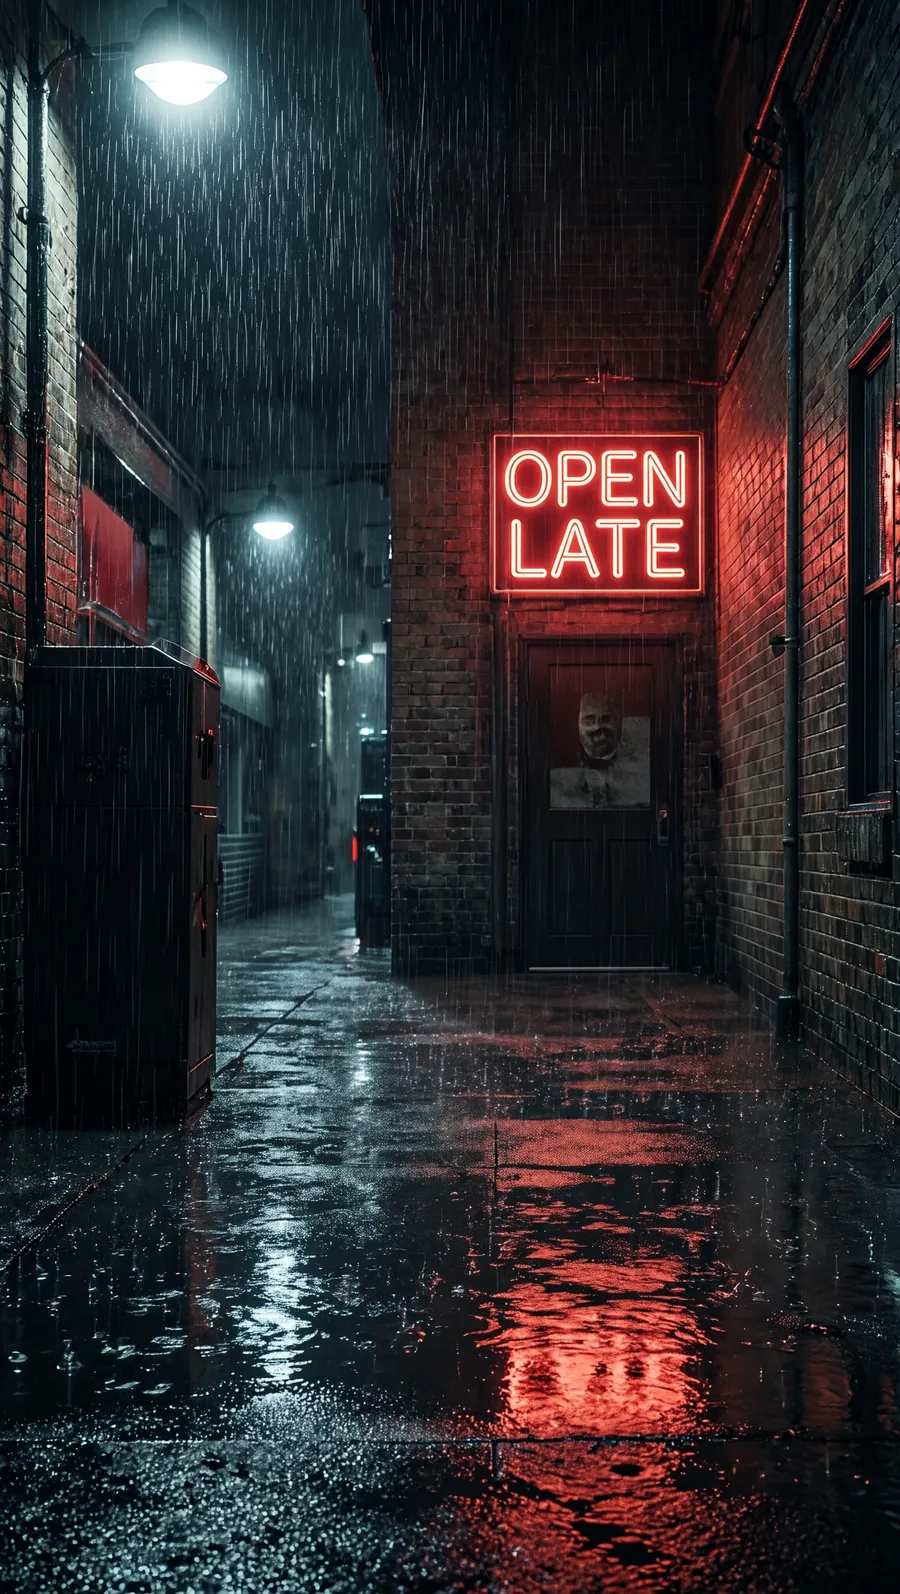
プロンプトを編集Neon sign
A rain-slicked alley at night with a red neon sign over a diner door that reads exactly "OPEN LATE". No other words anywhere in the frame
プロンプトを編集Paper set
A paper-cutout stop-motion set: a cardboard moon hanging on a string above layered paper waves, a tiny paper boat with a glowing lantern
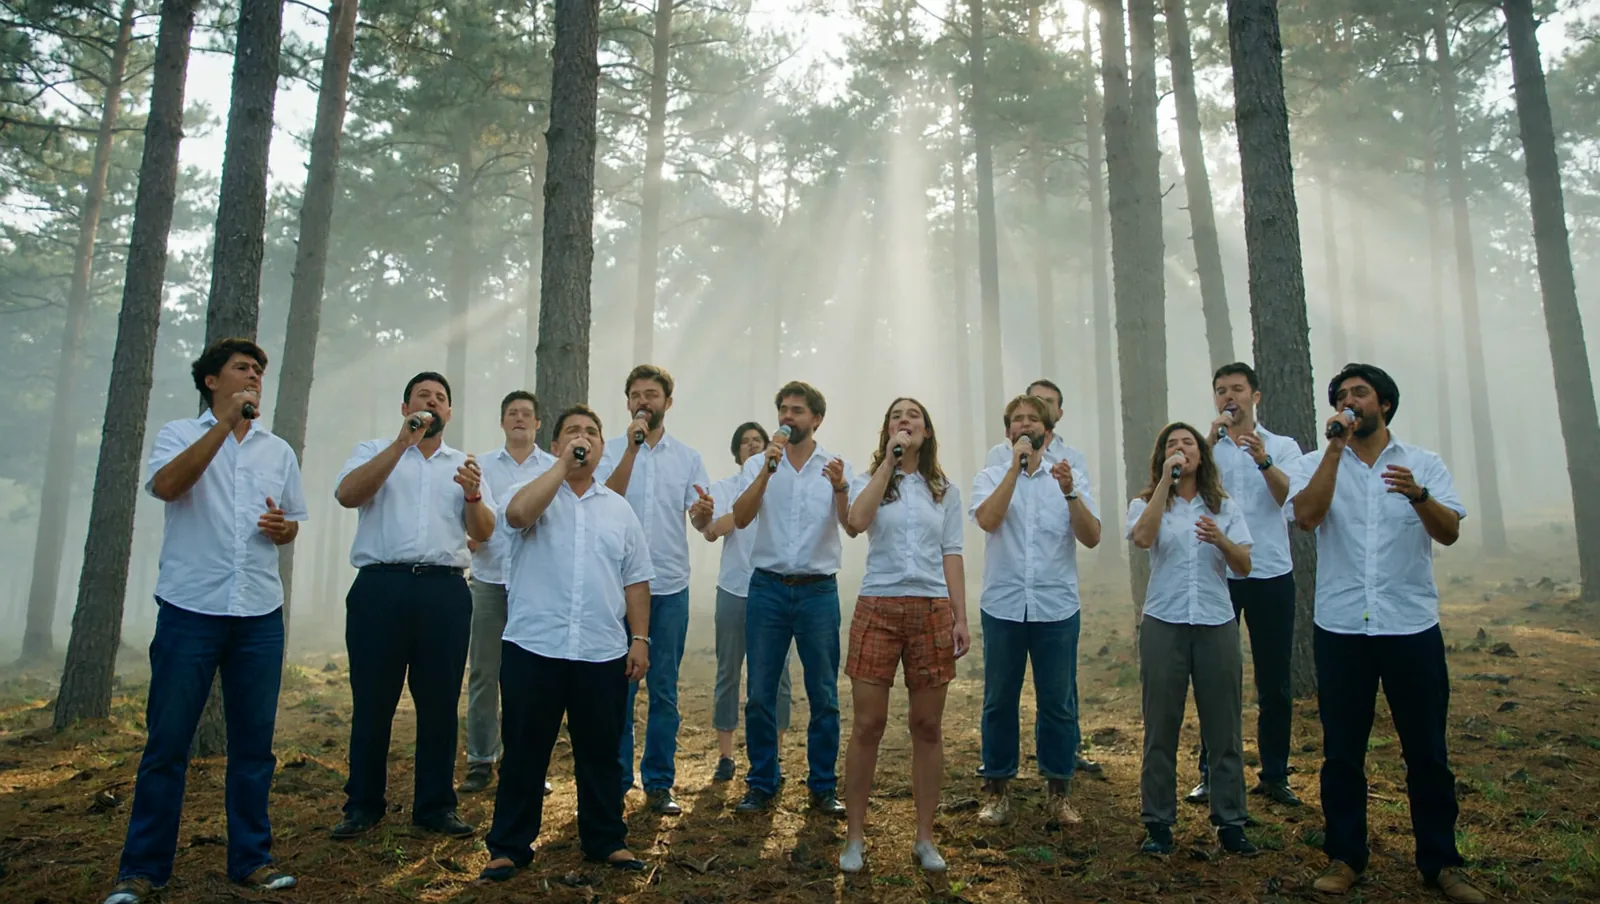
プロンプトを編集Forest choir
A dozen people in white shirts singing together in a misty pine forest in the morning, light beams through the trees, shot from low
プロンプトを編集ユースケース
Keyframes that keep the cast
Draw each shot of a verse from the same character sheet, and the singer looks like the same person on the bus, on the stage and on the roof.
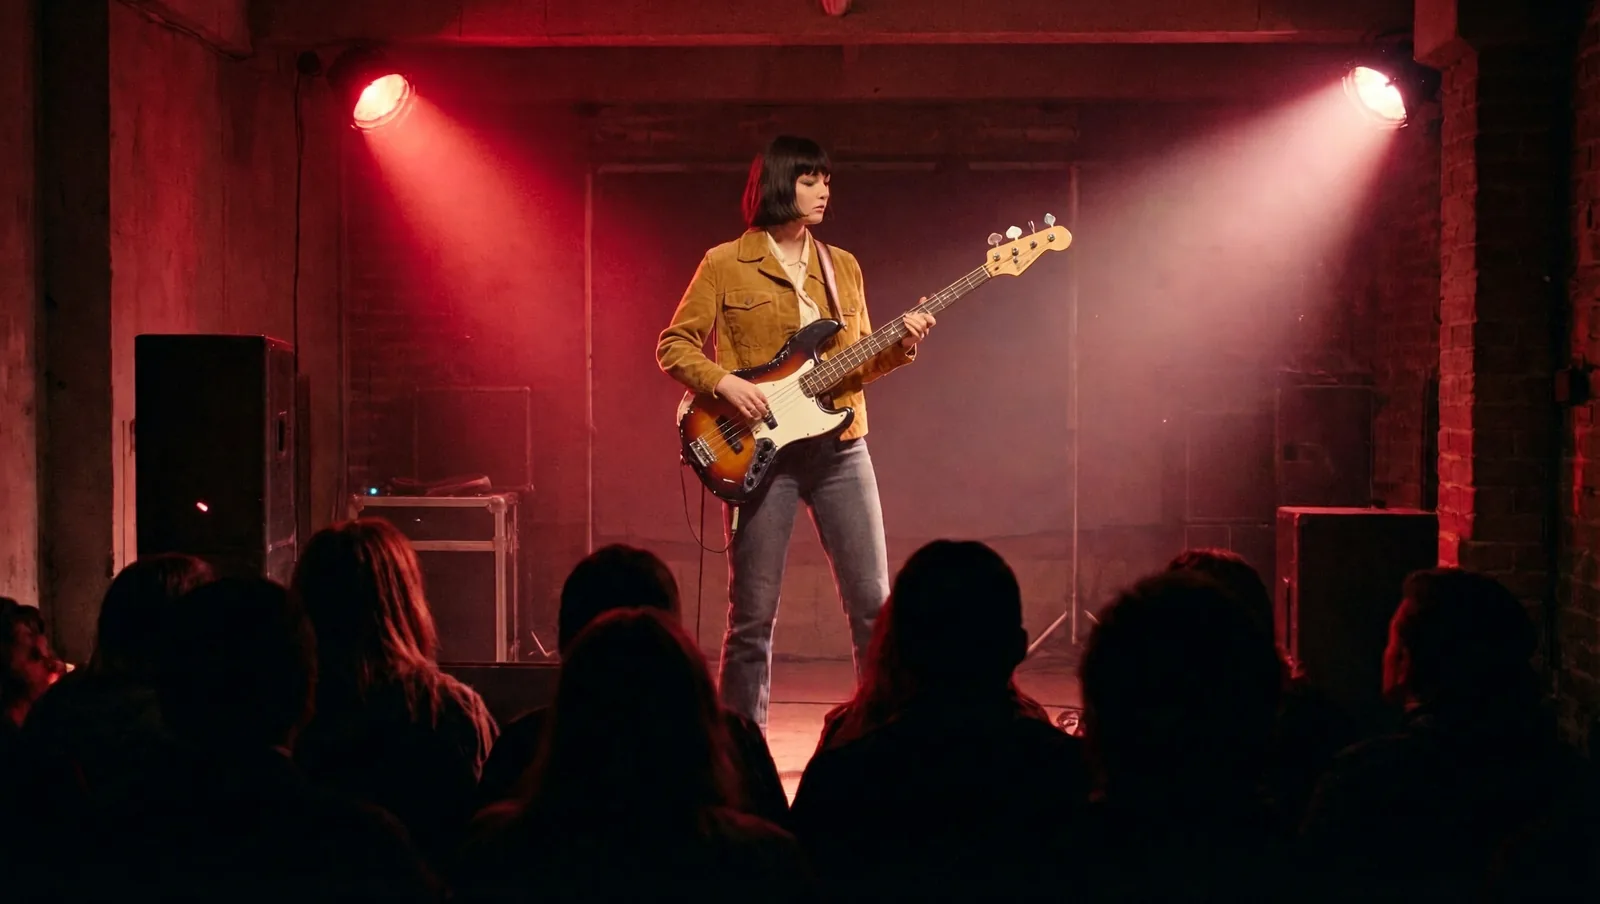
Live-show frames
Stage light, haze and a crowd in silhouette for the performance shots between the story scenes.
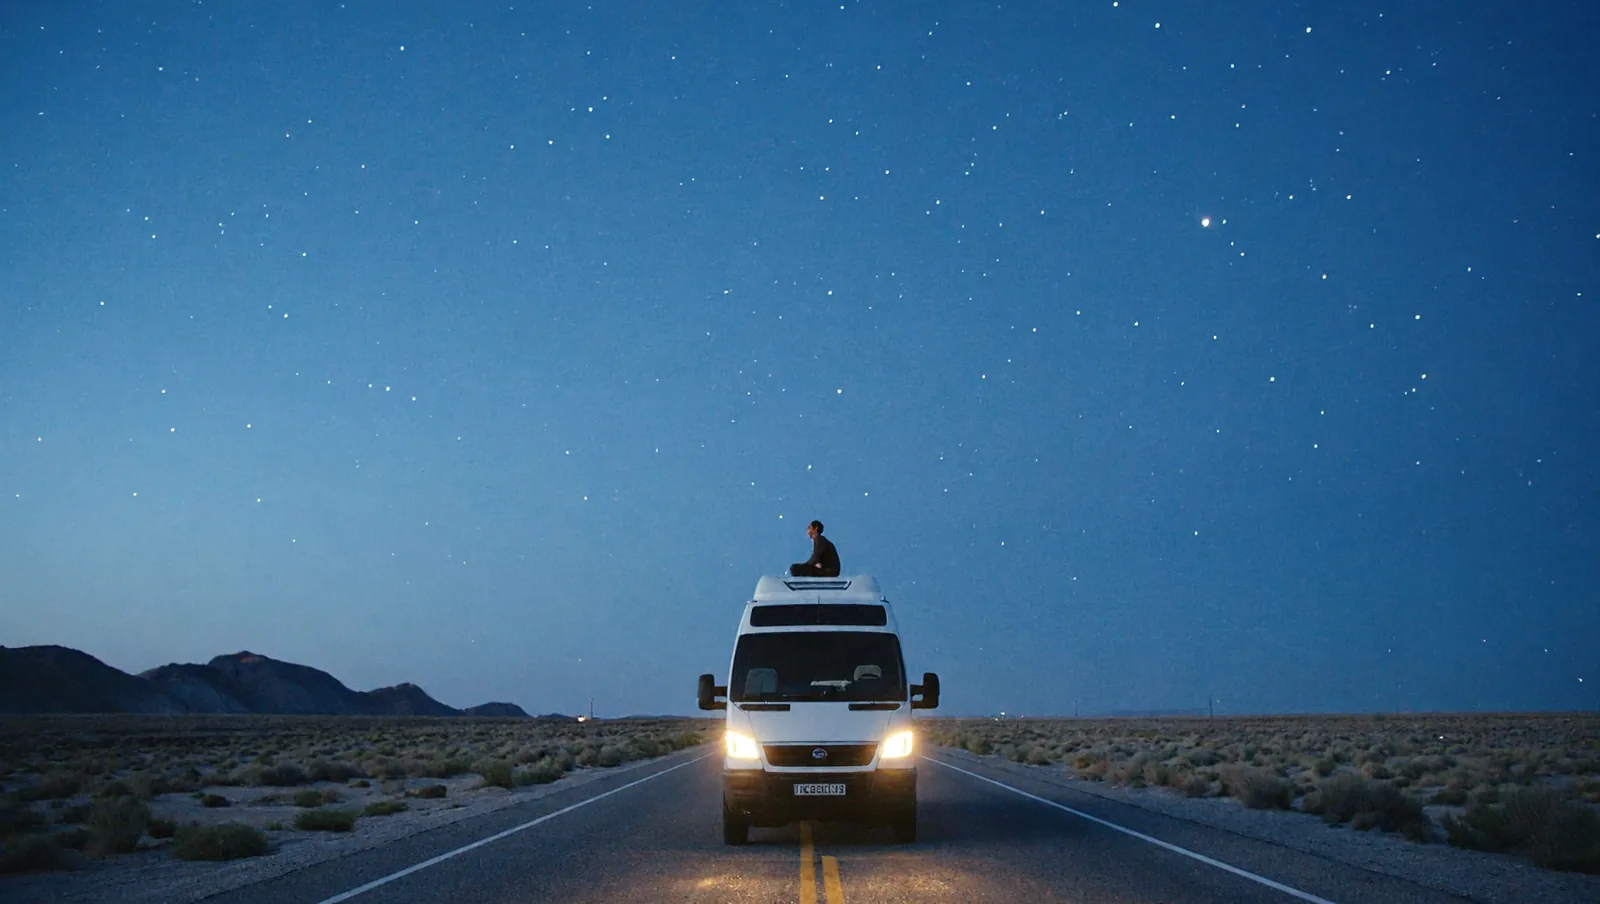
Wide establishing shots
Open a video on a place, like a desert road at blue hour, before the first face appears.
Character sheets
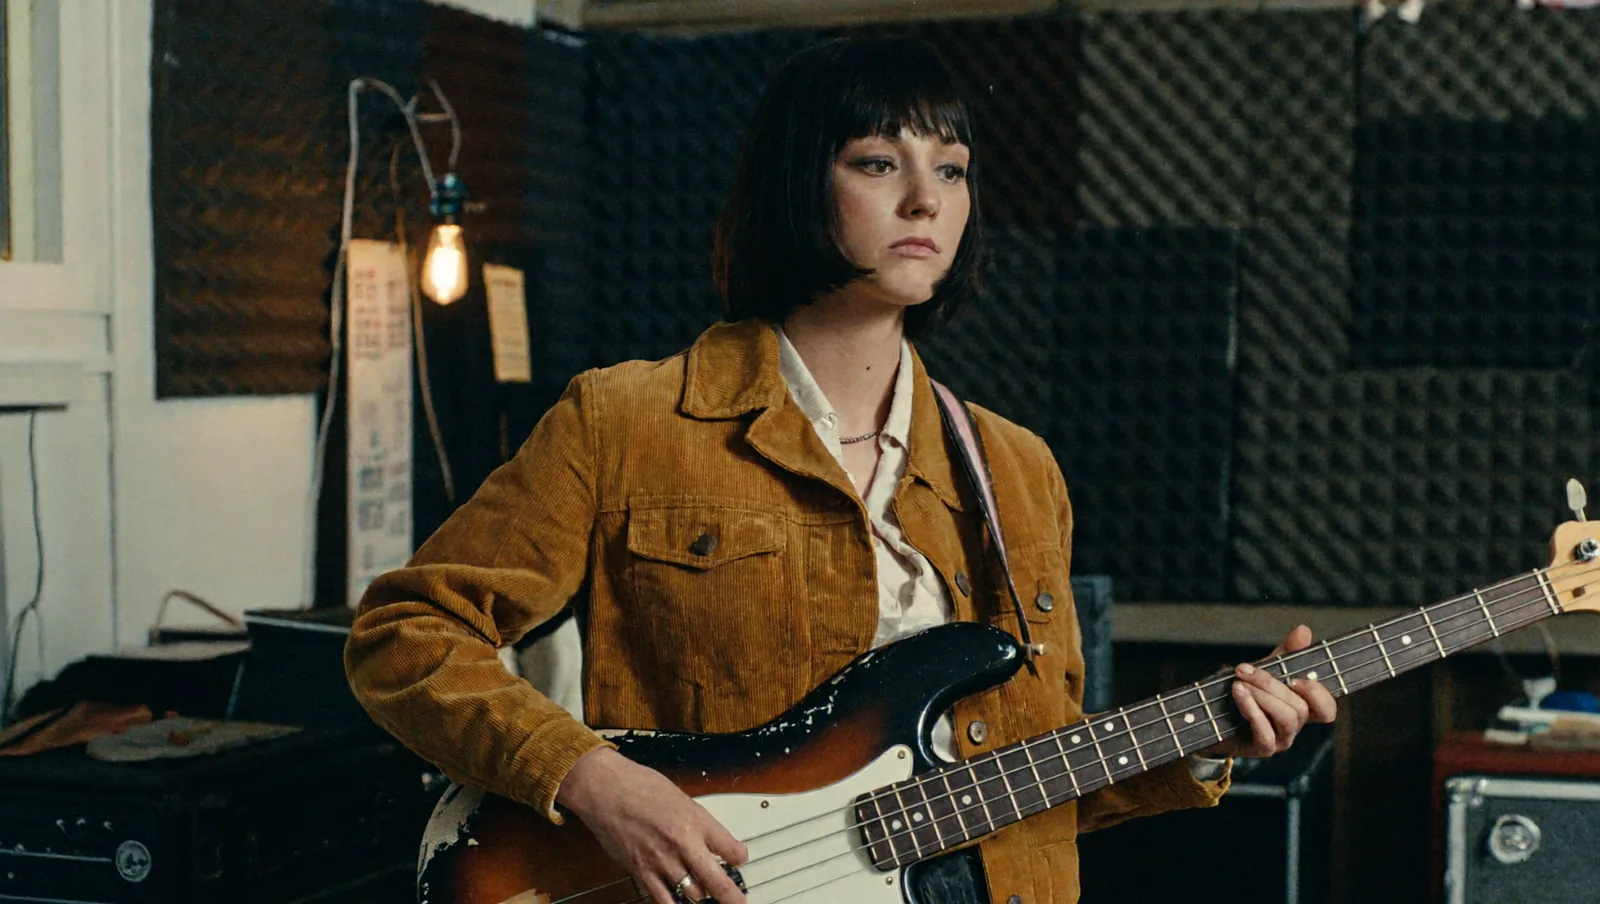
A clean, well-lit portrait of the lead is the reference every later frame is drawn from.
概要
MiniMax H3 Image is MiniMax's open-weights image model, built from the same family as its H3 video model. It turns a prompt into a picture, or edits from up to sixteen reference images at once, at native 1K, 2K or 4K. It is a 33-billion-parameter diffusion transformer that draws in six steps, which is why a 2K frame takes seconds rather than a minute.
Why sixteen references matter for a music video
A music video is dozens of frames of the same people in different places. Each frame needs the character sheet for every person in the shot, the location, and often the previous frame, so the light carries over. Most image models cap references at eight or fewer. Sixteen leaves room for a two-person shot without dropping anything.
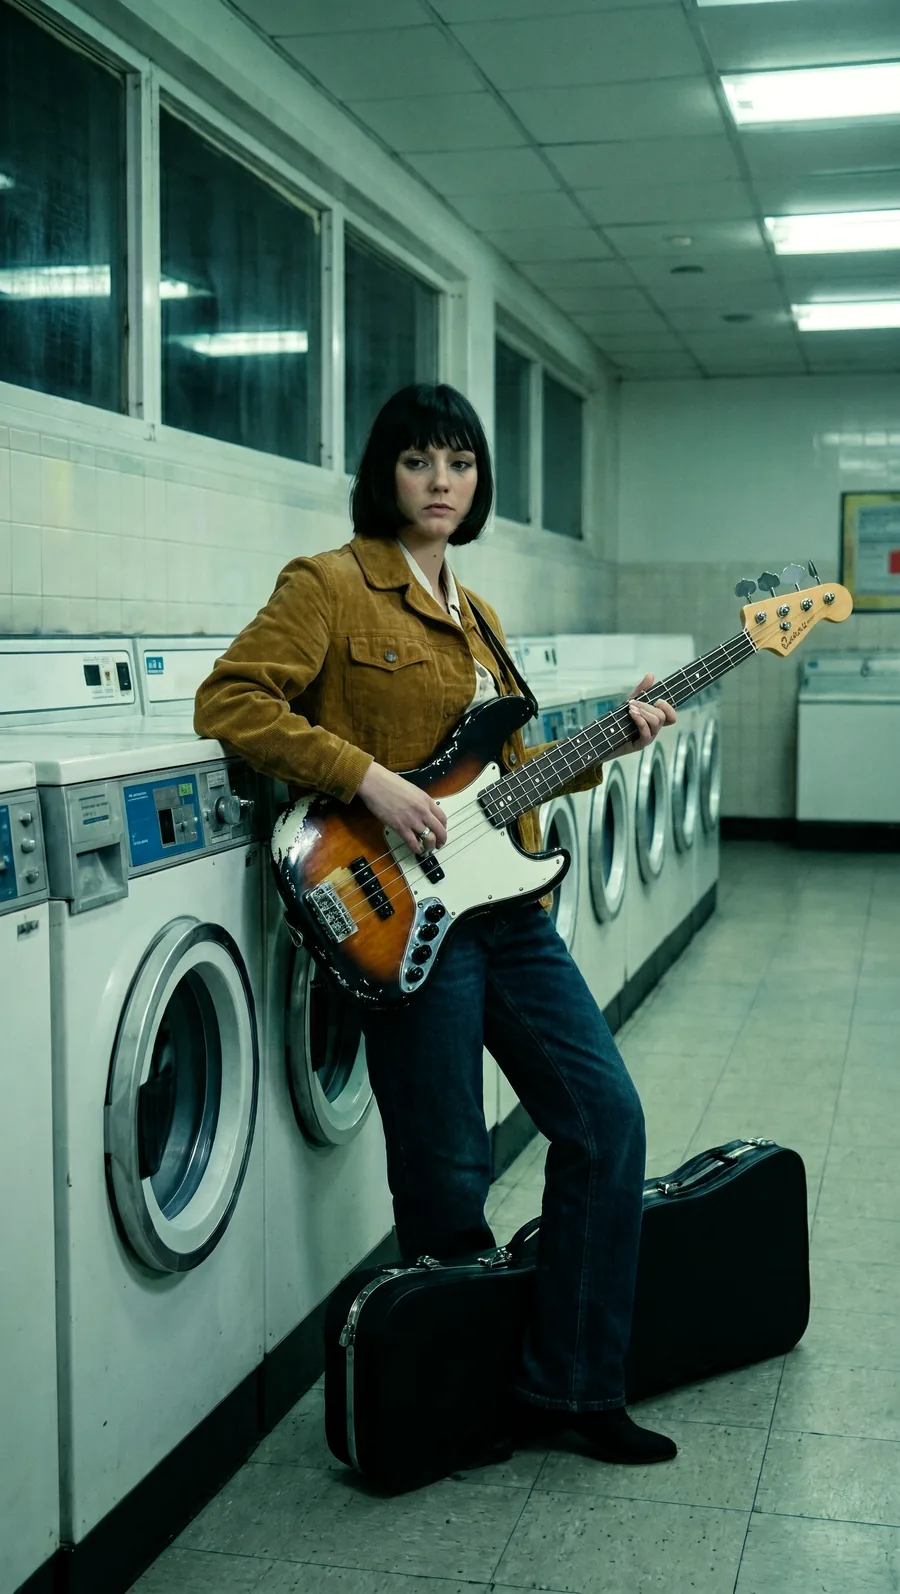
The four bassist frames on this page were drawn from one portrait: the same face, haircut, jacket and bass on a night bus, a rooftop, a laundromat and a stage.
Lettering and prompt rewriting
Kie, the API Dimly calls it through, rewrites prompts into a longer description by default. In our tests that rewriting once dropped a letter from the words we asked for, so Dimly always turns it off. With it off, short words came out right, but the model sometimes adds small made-up text around them, so Dimly keeps keyframes with lyrics in the frame on GPT Image 2.6.
MiniMax H3 Image and Dimly
Every Dimly music video starts as images: character sheets, look previews and one keyframe per shot, which a video model then animates. You don't pick the image model in the studio. Dimly's director draws with GPT Image 2.6 by default and can be switched to MiniMax H3 Image, which costs half the credits per keyframe and draws two to three times faster.
For the motion, see MiniMax H3, the video model from the same family.
シンプルな料金
動画のプランニングは無料。リリースのペースに合ったプランをお選びください。
Starter
Chorus Cut を 1 か月じっくり、または短めの楽曲を 1 本。
- 600 クレジット(30 日間有効)
- ≈ Chorus Cut 8 本(15 秒)
- または 2:20 までの楽曲 1 本
- 全モデル・全解像度 · 同時レンダリング 3 件
Pro
月 1 本のフルコーラスとリテイクの余裕。リリースに必要になったら、クレジットを追加できます。
月あたりのクレジット
- 1,000 クレジット(30 日間有効)
- ≈ Chorus Cut 14 本(15 秒)
- またはフル尺の楽曲 1 本(3:45)
- 全モデル・全解像度 · 同時レンダリング 4 件
Creator
月に複数本のフルコーラス、最大 4K に対応。
- 5,000 クレジット(30 日間有効)
- ≈ Chorus Cut 72 本(15 秒)
- またはフル尺の楽曲 約 5 本(3:45)
- 全モデル・全解像度 · 同時レンダリング 8 件
フルコーラス、Chorus Cut、リリックビデオ、ビジュアライザー · すべてのプランで透かしなしで書き出せます · 書き出し物の利用範囲は、ソースの権利と、生成に使ったモデル各社の規約によります
クレジットパック
1 回の支払いで、サブスクリプションは不要。AI エフェクト 1 本や 1 曲のために用意しました。継続してつくる予定なら、上のプランの方が割安です。
シングル
AI エフェクト動画 1 本(Hotel Lobby、AI Rap Duo など)。
- 250 クレジット(1 年間有効)
- AI エフェクト動画 1 本(Hotel Lobby、AI Rap Duo)
- または ≈ Chorus Cut 3 本(15 秒)
- 書き出しには Dimly の透かしが入ります
- サブスクリプション不要、自動更新なし
ソング
ミュージックビデオ 1 本(3:45 までの楽曲)、または AI エフェクト 4 本。
- 1,000 クレジット(1 年間有効)
- AI エフェクト動画 4 本(Hotel Lobby、AI Rap Duo)
- またはフル尺の楽曲 1 本(3:45)
- 透かしなしの書き出し
- サブスクリプション不要、自動更新なし
スタジオ
2K のフル尺 1 本と撮り直しの余裕、または楽曲 2 本。
- 2,000 クレジット(1 年間有効)
- AI エフェクト動画 8 本(Hotel Lobby、AI Rap Duo)
- またはフル尺の楽曲 約 2 本(3:45)
- 透かしなしの書き出し
- サブスクリプション不要、自動更新なし
見積りは MiniMax H3 768P、1 ショット 5 秒(15 秒の Chorus Cut は 3 ショット)、ショットごとにキーフレーム 1 枚、リファレンスシート 2 枚、撮り直しなしで計算しています。フル尺は 3:45 で、持ち込まれる楽曲の典型的な長さです。高い解像度やほかのモデルは 1 本あたりの費用が上がります。レンダリング前に正確な見積りを確認でき、失敗したレンダリングは返金されます。
よくある質問
MiniMax's open-weights image generation and editing model. It takes a prompt and up to sixteen reference images and draws one image at native 1K, 2K or 4K.
No. MiniMax H3 is the video model; H3 Image is the image model from the same family. In Dimly, an image model draws the keyframes and a video model such as MiniMax H3 animates them.
Not as a choice in the studio: you don't pick the image model. Dimly's director draws character sheets, look previews and keyframes with GPT Image 2.6 by default and can be set to use MiniMax H3 Image instead. Keyframes with lyrics in the frame stay on GPT Image either way.
One to sixteen, passed as public image URLs of up to 20 MB each. MiniMax refers to them in the prompt as Picture 1, Picture 2 and so on, in order.
Native 1K, 2K and 4K (about 1, 4 and 16 megapixels) in eleven aspect ratios from 21:9 to 9:16, or a custom width and height of up to 8,192 pixels a side.
Dimly generated them with MiniMax H3 Image at 2K on 15 November 2026, through the same Kie route the studio uses, and downscaled them for the web. The four bassist frames share one reference image, the rehearsal-room portrait.
その他のモデル
すべてのモデルを見るMiniMax H3
MiniMax
Reference-driven video with native stereo sound. Your track drives the picture, 768P up to 4K.
Seedance 2.5
ByteDance
First-and-last-frame moves up to thirty seconds, audio-driven at 480p/720p — your song muxed back intact.
Kling 4.0
Kuaishou
Kuaishou's long-take video model: up to thirty seconds in one pass, ten keyframes and Omni Reference with up to fifteen inputs.
Seedream 5.5
ByteDance Seed
ByteDance Seed's image model: natural skin and light, edits that leave the rest of the frame alone, and dense small text that stays legible.